A learned temporal detector, and the heuristics that beat it
Trained on six synthetic scenes, evaluated on two it never saw, and benchmarked against hand-written measurements on exactly the same clips.
Problem
CineQC scores video defects in the browser with hand-written measurements. The open question is whether a small learned model does better. The only way to answer it is to build one and compare the two on the same held-out data, through the same metric function, and publish whichever answer comes out.
Baseline
The baseline is the Artifact Lab heuristics: five measurements with thresholds calibrated on labelled fixtures. For this comparison they were recalibrated on the training and validation scenes only. Their published thresholds are fitted on all 48 clips, which include the 12 held out here — comparing against those would hand the baseline a look at the test set that the model never got, and the headline would mean nothing.
Data
48 synthetic clips: 8 scenes × 6 variants, one clean and five each carrying exactly one controlled defect. Split by whole scene, never by clip or window — variants of a scene share its background and windows overlap in time, so any finer split lets a model score well by recognising content it already trained on. Held out: scene-a, scene-h. Provenance and limits: dataset card.
Model and system
Three 3D convolution blocks into concatenated max and mean pooling, about 29k parameters, trained in 3.158s on an NVIDIA GeForce RTX 4080 SUPER with PyTorch 2.13.0+cu126 and CUDA 12.6. Two choices carry it: the input is each window stacked with its own temporal first difference, and pooling is max as well as mean. An earlier version used average pooling alone and predicted "defective" for every held-out window — it had learned the 5:1 class prior rather than the defects. Details: model card.
Evaluation
Both systems scored at clip level on the same 12 held-out clips, through the same recompute_classification_metrics over saved predictions. The threshold came from validation only.
| System | Precision | Recall | F1 | Accuracy |
|---|---|---|---|---|
| Artifact Lab heuristics | 1.00 | 1.00 | 1.00 | 1.00 |
| Learned detector | 0.90 | 0.90 | 0.90 | 0.83 |
The heuristics win outright, 1.00 against 0.90 — and they are faster, need no GPU, and say which defect they found. Where defects are synthetic, isolated, and known in advance, that is the expected result, and it is the reason to keep a heuristic layer rather than replace it. The argument for the learned path is the opposite case: heuristics only catch artifacts somebody thought to write a measurement for.
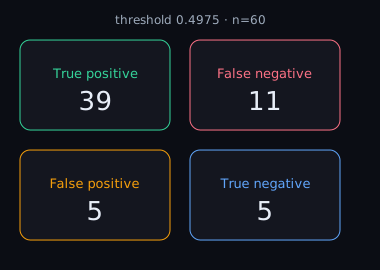
At window level the model scores F1 0.83 across 60 windows (precision 0.886, recall 0.78). Confusion matrix · every decision.
Failure gallery
16 window errors at threshold 0.4975, by defect family:
none— 5detail-collapse— 5color-drift— 2duplicate-stutter— 2flicker— 2
detail-collapse is the weakest family: progressive blur reads as ordinary softness once a window is downsampled to 128×72. The errors on clean windows are the model's remaining bias towards the defect class. Full list: error-gallery.json.
Limitations
- Eight synthetic scenes with one property varying at a time. A held-out result rests on 2 scenes and 12 clips; a few points either way is noise.
- The model has never seen a frame of real footage. Compression artifacts, grain, and real motion blur are absent from training.
- It returns one score and does not name the defect. The heuristics do.
- Scores order samples; they are not calibrated probabilities.
- Peak VRAM 812 MiB — a fact about this model at this size, not about the approach.
Next steps
- Label by defect family rather than binary, so the model can say what it found.
- Vary defect strength across a range; nothing here says anything about a defect at half this intensity.
- Introduce real footage with real compression before making any claim about production behaviour.
- Re-run the comparison once the fixture set is large enough that a few points is a signal.
Repository and reproduction
Package, cards, and the committed run: temporal-detector.
uv run --project creative-ai-engineering/capstones/temporal-detector python -m temporal_detector.train --out runs/local-rtx4080 --device cudauv run --project creative-ai-engineering/capstones/temporal-detector python -m temporal_detector.benchmark --run runs/local-rtx4080--device cuda exits non-zero when CUDA is unavailable rather than falling back, so a CPU run can never be filed as GPU evidence. Config hash a7fc6fac6152, dataset hash 0cc7863a34af, checkpoint 62976b372a69.
Defence
The result worth being asked about is the one where my model loses. I would keep it. The comparison was only worth running because it could come out this way, and the honest reading is that a hand-written measurement is the right tool for a defect you can define, while a learned model earns its place on the defects nobody wrote a measurement for. Publishing only the flattering half would have made the whole exercise decorative.