PyTorch and transfer learning
Train a small baseline you can resume and reproduce.
- Use tensors, devices, datasets, data loaders, modules, losses, optimizers, and training loops.
- Apply transfer learning and fine-tuning to modest datasets.
- Reproduce checkpoints, seeds, configuration, cloud validation, and local RTX 4080 execution.
Explain each stage of a training loop and how a checkpoint supports reproducibility.
Train one modest, reproducible baseline. Required route: tensors and data (75 min), model lifecycle (90 min), transfer learning (60 min), cloud run (70 min), resume/reproduction (55 min), transfer/evidence (70 min). Total: 7 hours, including selected official PyTorch reading.
Entry diagnostic
Narrate zero_grad → forward → loss → backward → step. Then explain why evaluation uses both model.eval() and disabled gradient tracking.
Self-check
What mismatch is likely when an image batch is shaped N,H,W,C but a vision Module expects N,C,H,W?
Why this matters in CineQC
PyTorch APIs are useful only when the lifecycle is visible. CineQC needs a baseline whose inputs, device, split, checkpoint, and configuration can be inspected, resumed, and reproduced—not a notebook with one lucky score.
Visual model — data to checkpoint
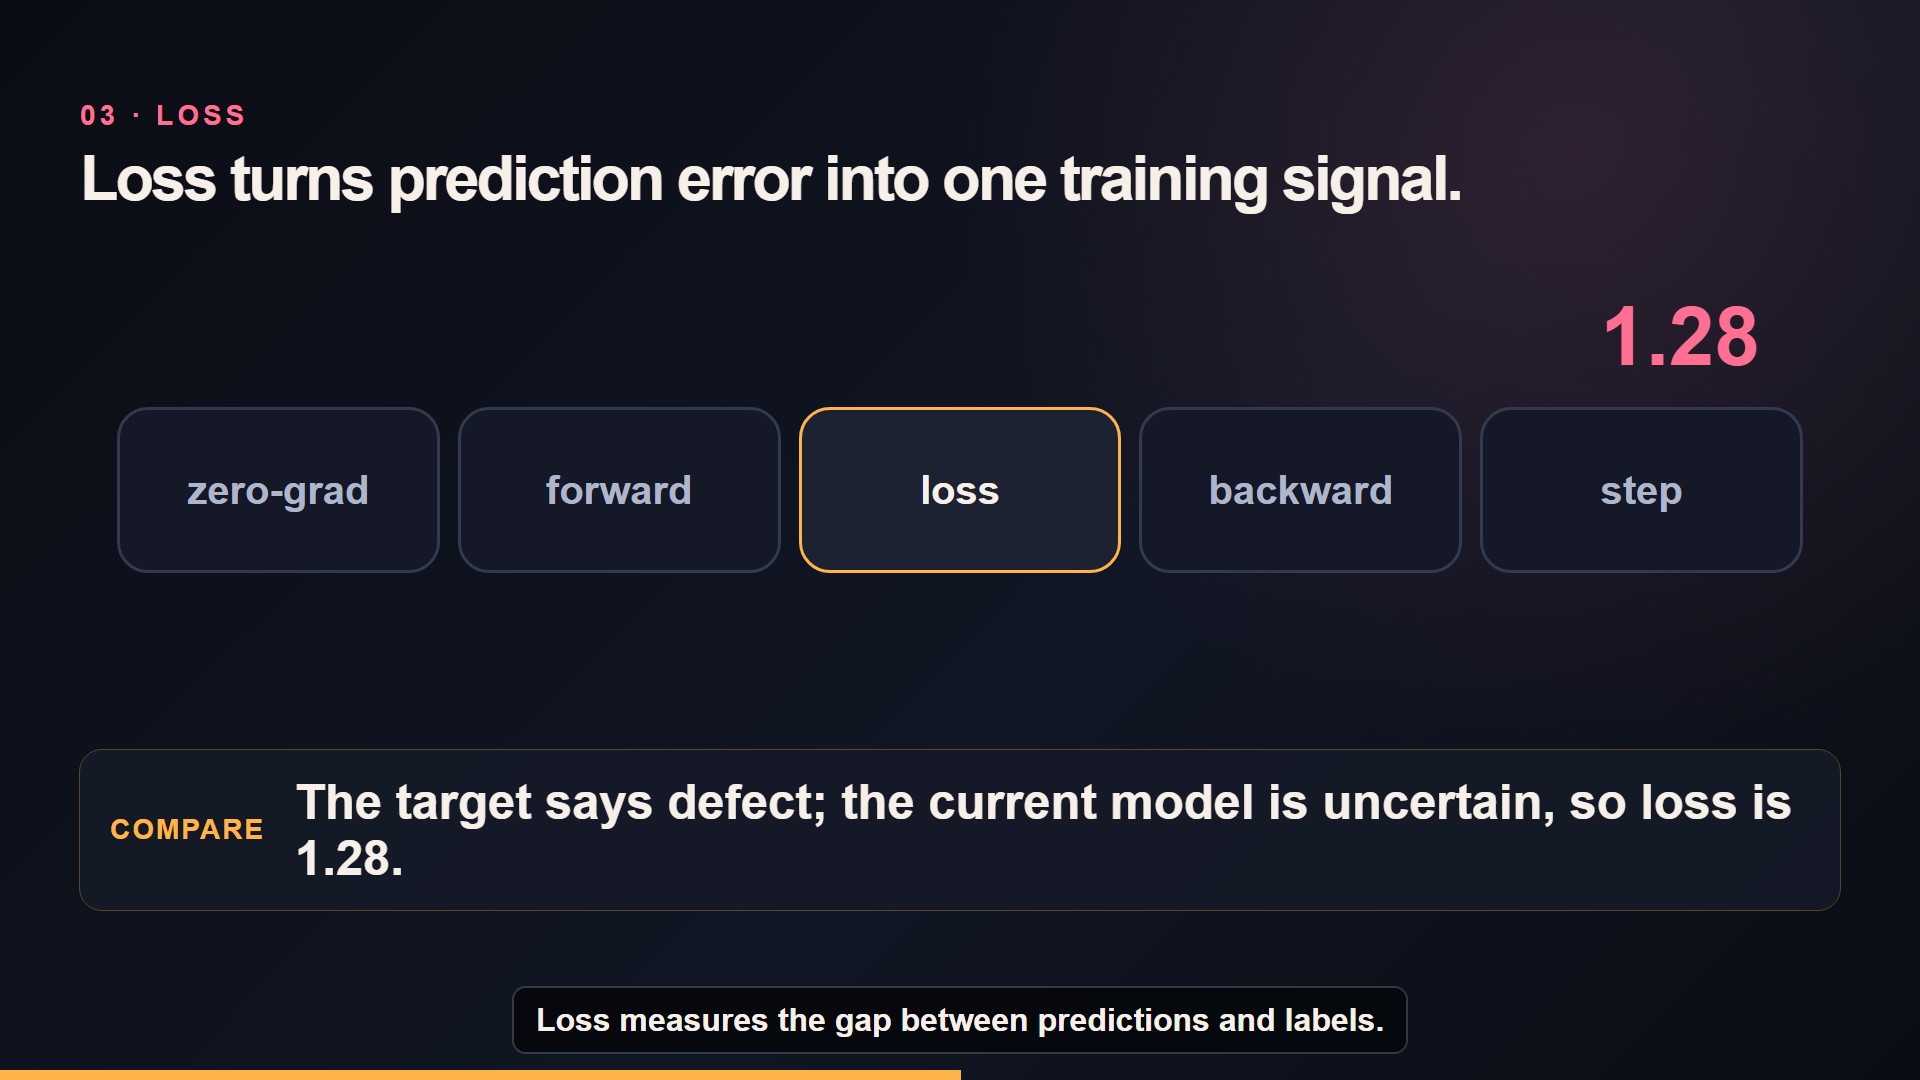
Complete five-stage training loop with before-and-after parameter evidence. If the video cannot play, this image and the transcript preserve the complete teaching claim.
Follow Dataset → DataLoader → tensor/device → Module → loss → optimizer → checkpoint. A Dataset returns one sample and label. A DataLoader batches and optionally shuffles training samples. A Module owns parameters and defines forward. Loss measures error; the optimizer updates parameters.
Runtime: Local Python 3.12 · PyTorch 2.x · CPU-safe tiny data · 25 min.
import random
import torch
from torch import nn
from torch.utils.data import DataLoader, TensorDataset

random.seed(7)
torch.manual_seed(7)
device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
x = torch.tensor([[0., 0.], [0., 1.], [1., 0.], [1., 1.]])
y = torch.tensor([0, 1, 1, 1])
loader = DataLoader(TensorDataset(x, y), batch_size=2, shuffle=True,
                    generator=torch.Generator().manual_seed(7))
model = nn.Sequential(nn.Linear(2, 4), nn.ReLU(), nn.Linear(4, 2)).to(device)
loss_fn = nn.CrossEntropyLoss()
optimizer = torch.optim.SGD(model.parameters(), lr=0.1)

model.train()
for features, labels in loader:
    features, labels = features.to(device), labels.to(device)
    optimizer.zero_grad()
    logits = model(features)
    loss = loss_fn(logits, labels)
    loss.backward()
    optimizer.step()
print(device.type, round(float(loss.detach()), 4))
Call model.train() for training behavior and model.eval() for validation behavior. torch.no_grad() prevents graph construction; it does not switch dropout or batch normalization. Save model and optimizer states, epoch, best validation metric, label map, seed, and config. Load them before resuming.
Runtime: Local Python 3.12 · PyTorch 2.x · CPU-safe tiny data · 20 min.
import io
import torch

model = torch.nn.Linear(2, 2)
optimizer = torch.optim.SGD(model.parameters(), lr=0.05)
checkpoint = {"epoch": 3, "model": model.state_dict(),
              "optimizer": optimizer.state_dict(), "seed": 7,
              "config": {"lr": 0.05, "labels": ["clean", "artifact"]}}
buffer = io.BytesIO()
torch.save(checkpoint, buffer)
buffer.seek(0)
restored = torch.load(buffer, map_location="cpu", weights_only=True)
model.load_state_dict(restored["model"])
optimizer.load_state_dict(restored["optimizer"])
assert restored["config"]["labels"] == ["clean", "artifact"]
print("resume epoch", restored["epoch"] + 1)
Self-check
Why must an optimizer checkpoint be restored as well as model weights when training resumes?
Transfer learning, bounded
Start with a documented pretrained vision backbone. Replace the classification head, freeze the backbone for a short head-only run, then optionally unfreeze the final block at a smaller learning rate. Record the exact weights identifier and preprocessing. Do not train a large video architecture from scratch in this milestone.
Use the selected official PyTorch transfer-learning tutorial to inspect freezing, fine-tuning, and train/eval handling. A short fast.ai Lesson 1 segment is optional inspiration, not a second course.
Sandbox lab
Run cloud-first on Kaggle or another notebook GPU using only the lawful dataset fixture. Pin dependencies, copy the config into the output, save a checkpoint, stop the session, resume for one epoch, and export predictions. Also run a CPU-safe one-batch test so shape and lifecycle failures do not require a GPU.
Then reproduce locally on the RTX 4080: create the same environment, verify torch.cuda.is_available(), record GPU and PyTorch/CUDA versions, use the same seed/config/data checksum, and compare metrics within a declared tolerance. CUDA kernels can remain nondeterministic; state that limitation instead of promising bitwise equality.
Runtime: Local PowerShell · RTX 4080 verification; CPU fallback prints device · 10 min.
python -c "import torch; print({'torch':torch.__version__,'cuda':torch.cuda.is_available(),'device':torch.cuda.get_device_name(0) if torch.cuda.is_available() else 'cpu'})"Failure clinic
Diagnose stale accumulated gradients, validation performed in train mode, a checkpoint missing optimizer/config state, different label order after resume, shuffled validation data, pretrained weights paired with wrong normalization, and CUDA out-of-memory hidden by an oversized batch. Repair by making each contract explicit and testing one batch first.
CineQC transfer
Export a small inference contract: ordered label map, expected sequence shape/dtype/range, preprocessing version, checkpoint identity, and output logits/probabilities. Keep training outside production. Compare cloud and local predictions on the same public fixture before connecting any private CineQC path.
Self-check
Which evidence distinguishes reproducibility from repetition: matching data/config/checkpoint identities plus a declared numerical tolerance, or merely pressing Run twice?
Evidence gate
Submit a modest baseline that you can train, resume, reproduce, and explain. Include the config, environment record, dataset checksum, checkpoint with optimizer state, saved predictions, CPU one-batch test, cloud run log, local RTX 4080 reproduction, metric tolerance, and a narrated lifecycle. Report limitations and do not claim generalization beyond the fixed benchmark.
One-page summary
- Dataset and DataLoader make sample and batch contracts explicit.
- Move both model and batches to the same device.
- Zero gradients before forward/loss/backward/step.
- Train/eval modes and gradient tracking solve different problems.
- Checkpoints need model, optimizer, epoch, config, labels, and seed.
- Transfer learning is the bounded baseline; training from scratch is optional and excluded.
- Cloud-first proves the loop; the RTX 4080 reproduction proves portability within tolerance.
Read the selected fine-tuning, freezing, and train/eval lifecycle sections used by the baseline. · 35 min
Optionally watch only the image-classifier workflow segment for a second view of transfer learning; skip the rest for now. · 25 min
Train a small baseline, resume it, reproduce its result, and explain the loop.
Check the statements you can demonstrate in the challenge. Selections route your learning; they are not proof of mastery.
Start the full milestone.
Submit an inspectable artifact for independent review. Only a verified diagnostic challenge or reviewed evidence can mark this milestone proven. Proof is local self-tracking, not tamper-resistant against edits to this browser storage.
- Run and resume the modest transfer-learning baseline from a complete checkpoint.
- Reproduce cloud and local RTX 4080 runs within a declared tolerance.
- Run and explain the tensor, device, data loader, module, loss, optimizer, and training loop lifecycle.
Current state: not-started. Advance through learning, practice, and submitted evidence; proof requires a later passed review.
Your local study notes mount here when JavaScript is available.
Teaching modes mount here when JavaScript is available. The readable course remains available without them.